Route smarter,Pay less.
An OpenAI-compatible gateway that classifies each request by how much reasoning it needs and routes to the cheapest capable model. In-process classification in ~16ms, zero network hops. Change your base URL and nothing else.
Three gates before a model is called
Orange sits between your application and your model providers. Each gate can make the call cheaper, or skip it entirely.
Exact-match cache
Hashes the whole conversation plus generation parameters that change what a valid answer is. A hit returns with zero classification and zero model calls. 0% false positives by construction.
Complexity classifier
Embeds the newest turn locally in-process and scores against human-reviewed golden tiers. Fast p50 16.2ms latency. Only 12.8% borderline requests escalate to a judge model.
Failover & governance
A model that times out, rate-limits or 5xxs falls down the cost ladder — never up. Named request model serves as an absolute cost ceiling. Per-key budgets and circuit breakers per provider.
Stop this madness 🤦♂️, route intelligently
It’s a whole genre at this point. What are we doing...
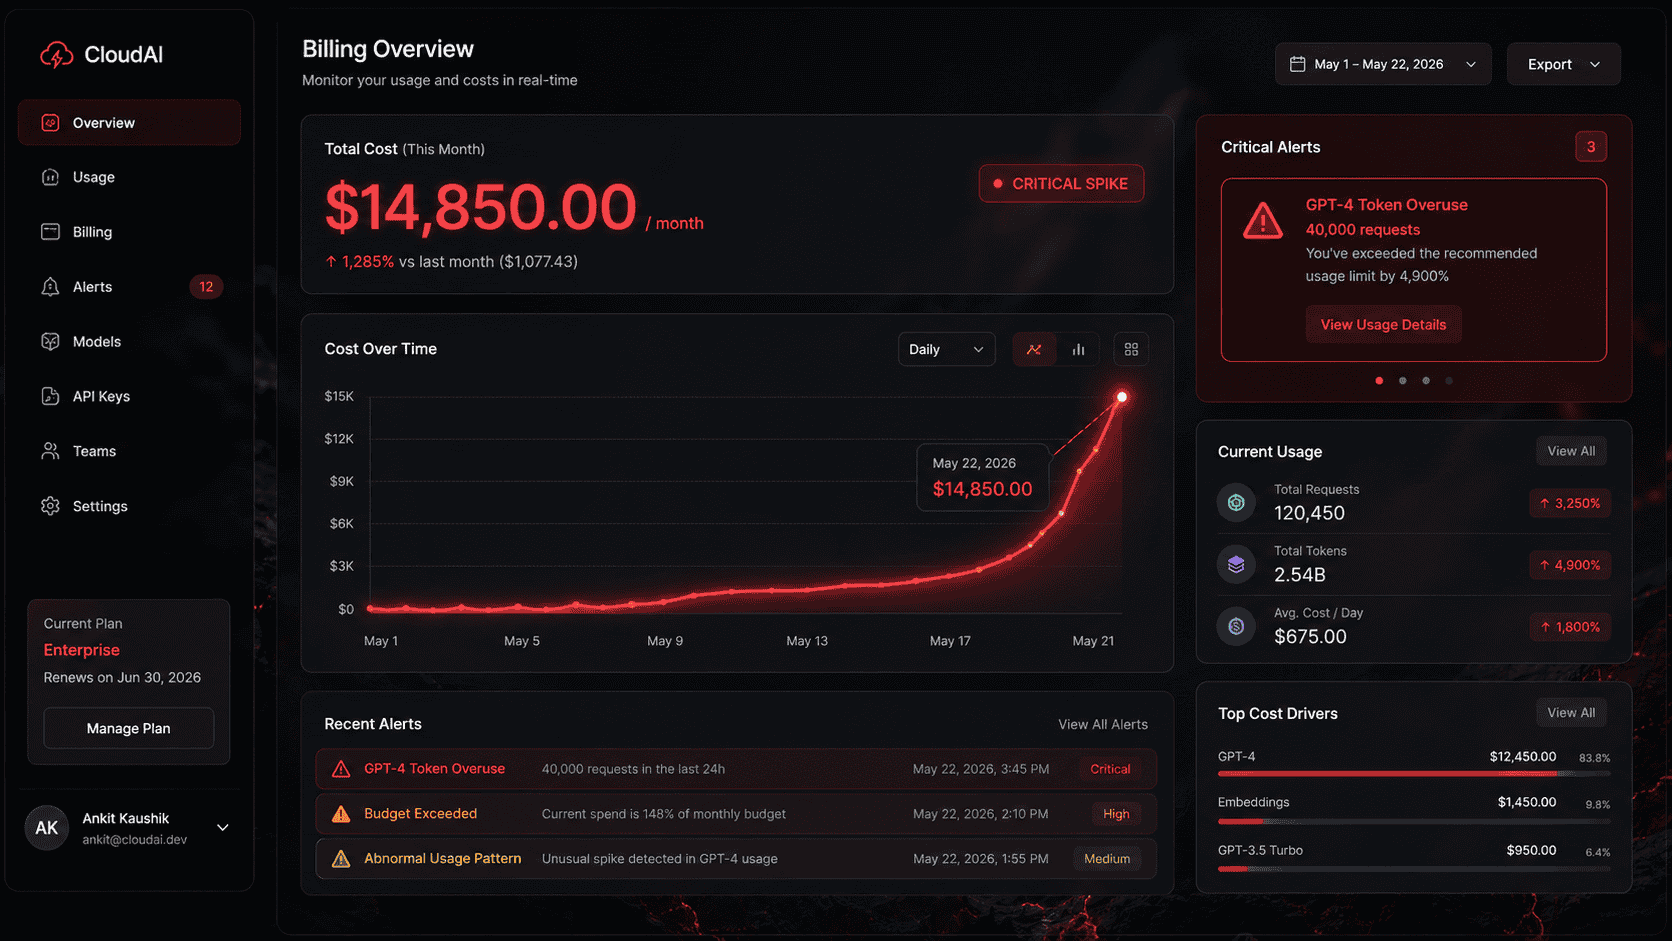
Got the monthly bill. We spent four figures sending 'extract the date from this string' to a frontier model. Forty thousand times. I need to lie down.
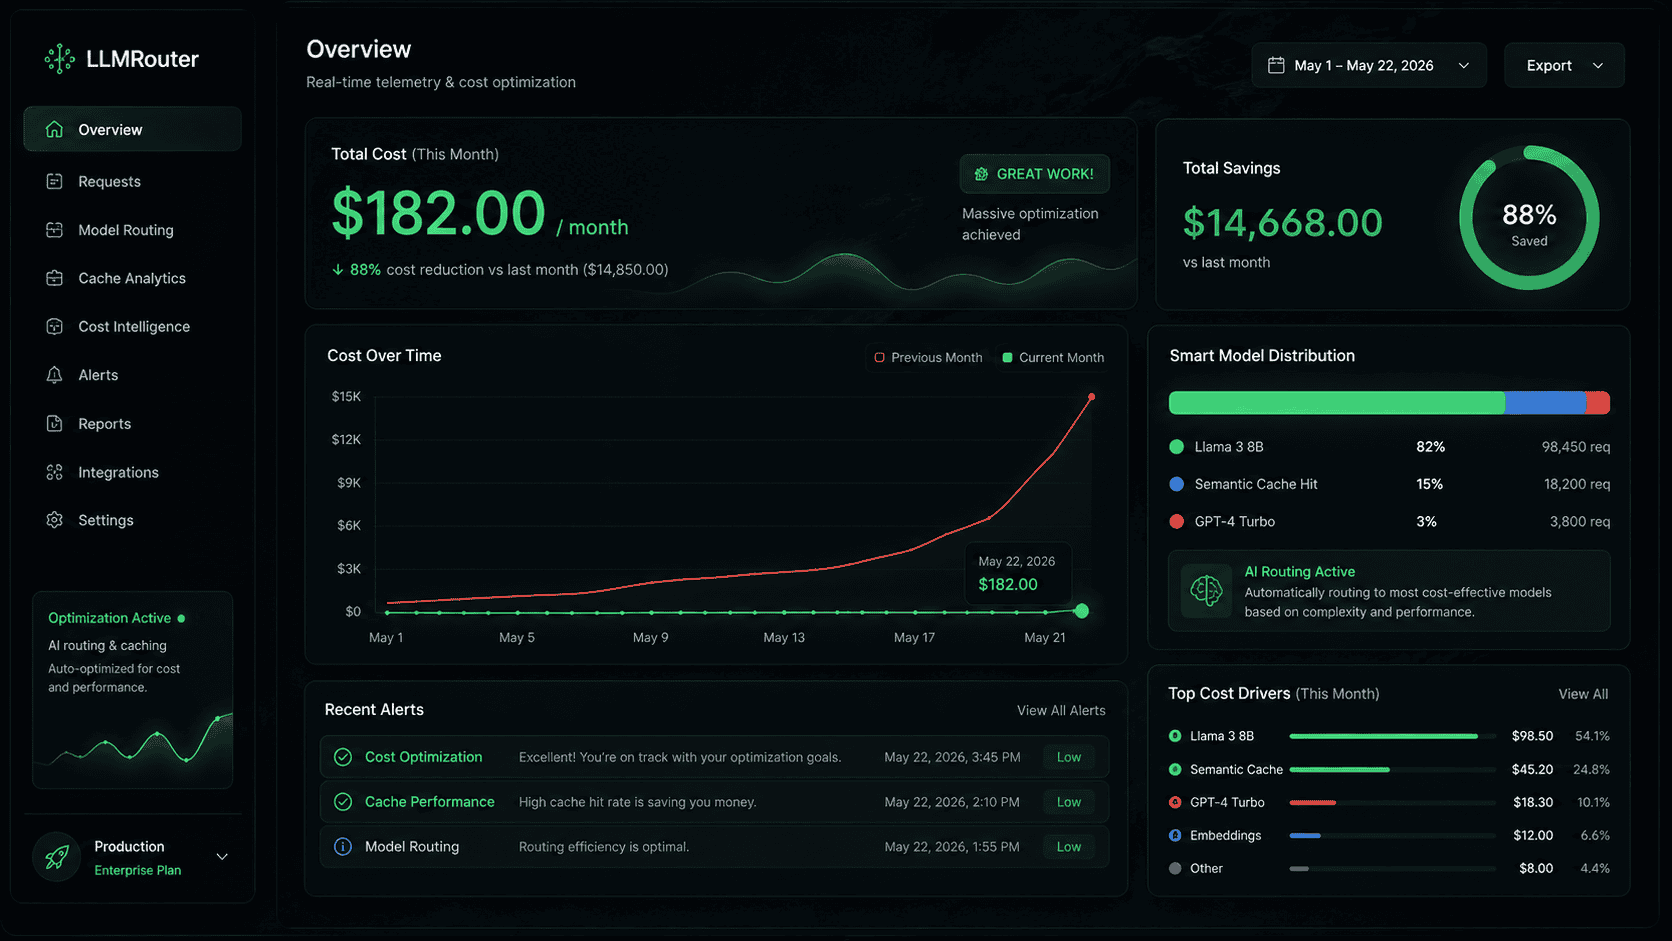
Why does classifying a boolean take four seconds? Because we send everything to the biggest model we have, and nobody wants to be the person who changed it.
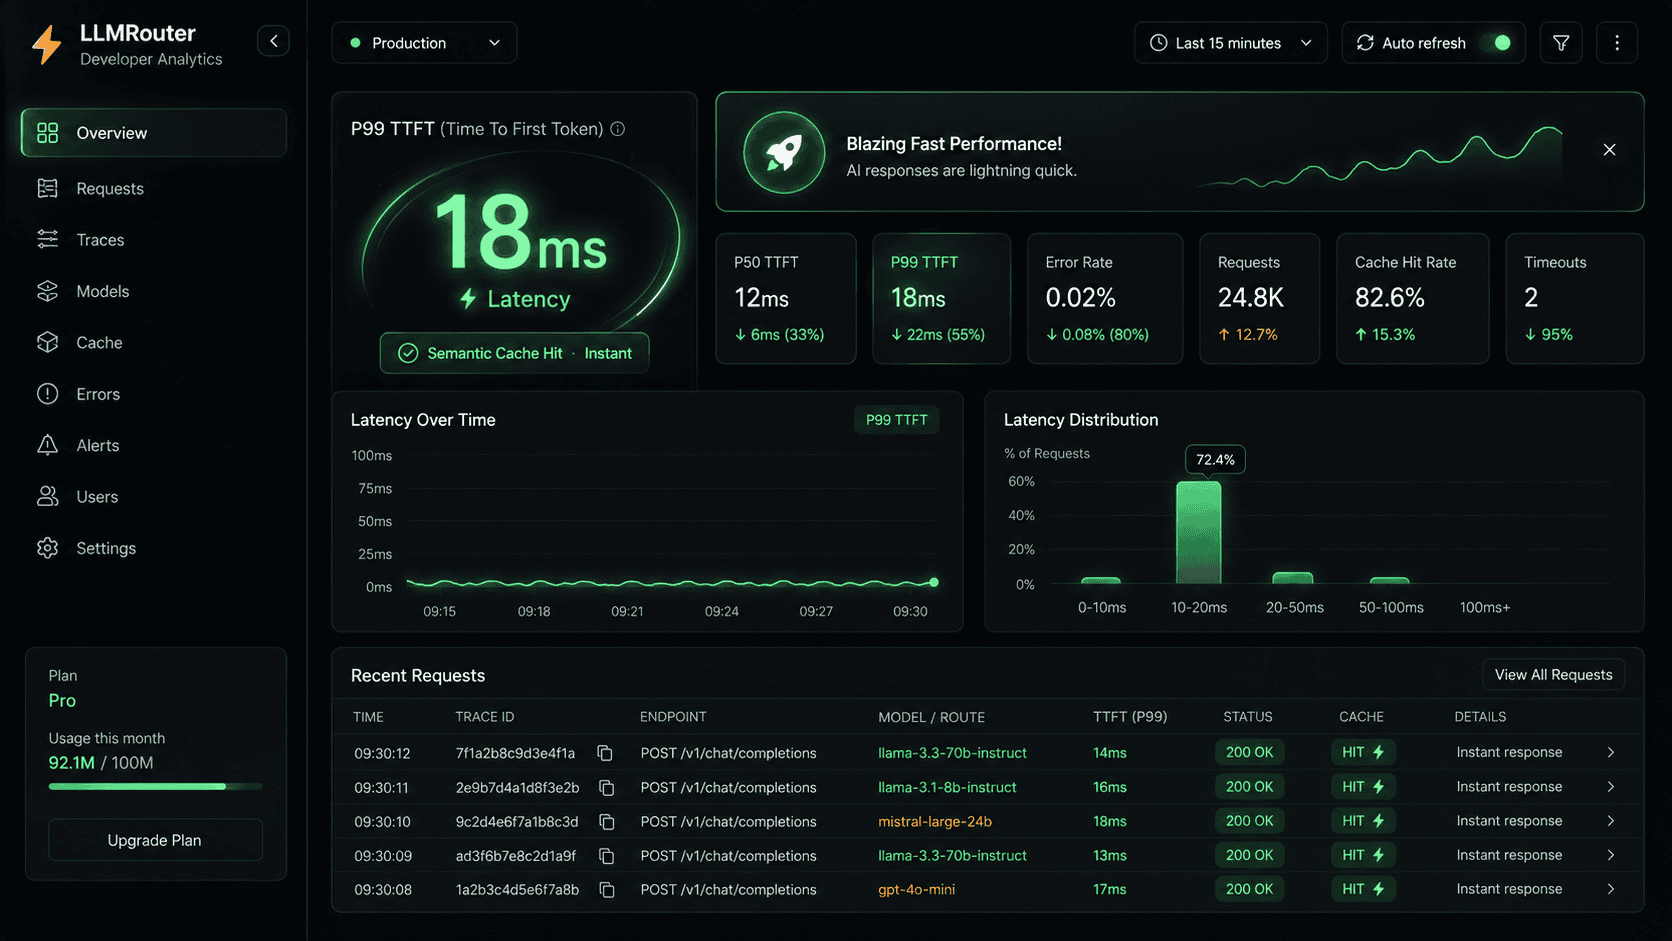
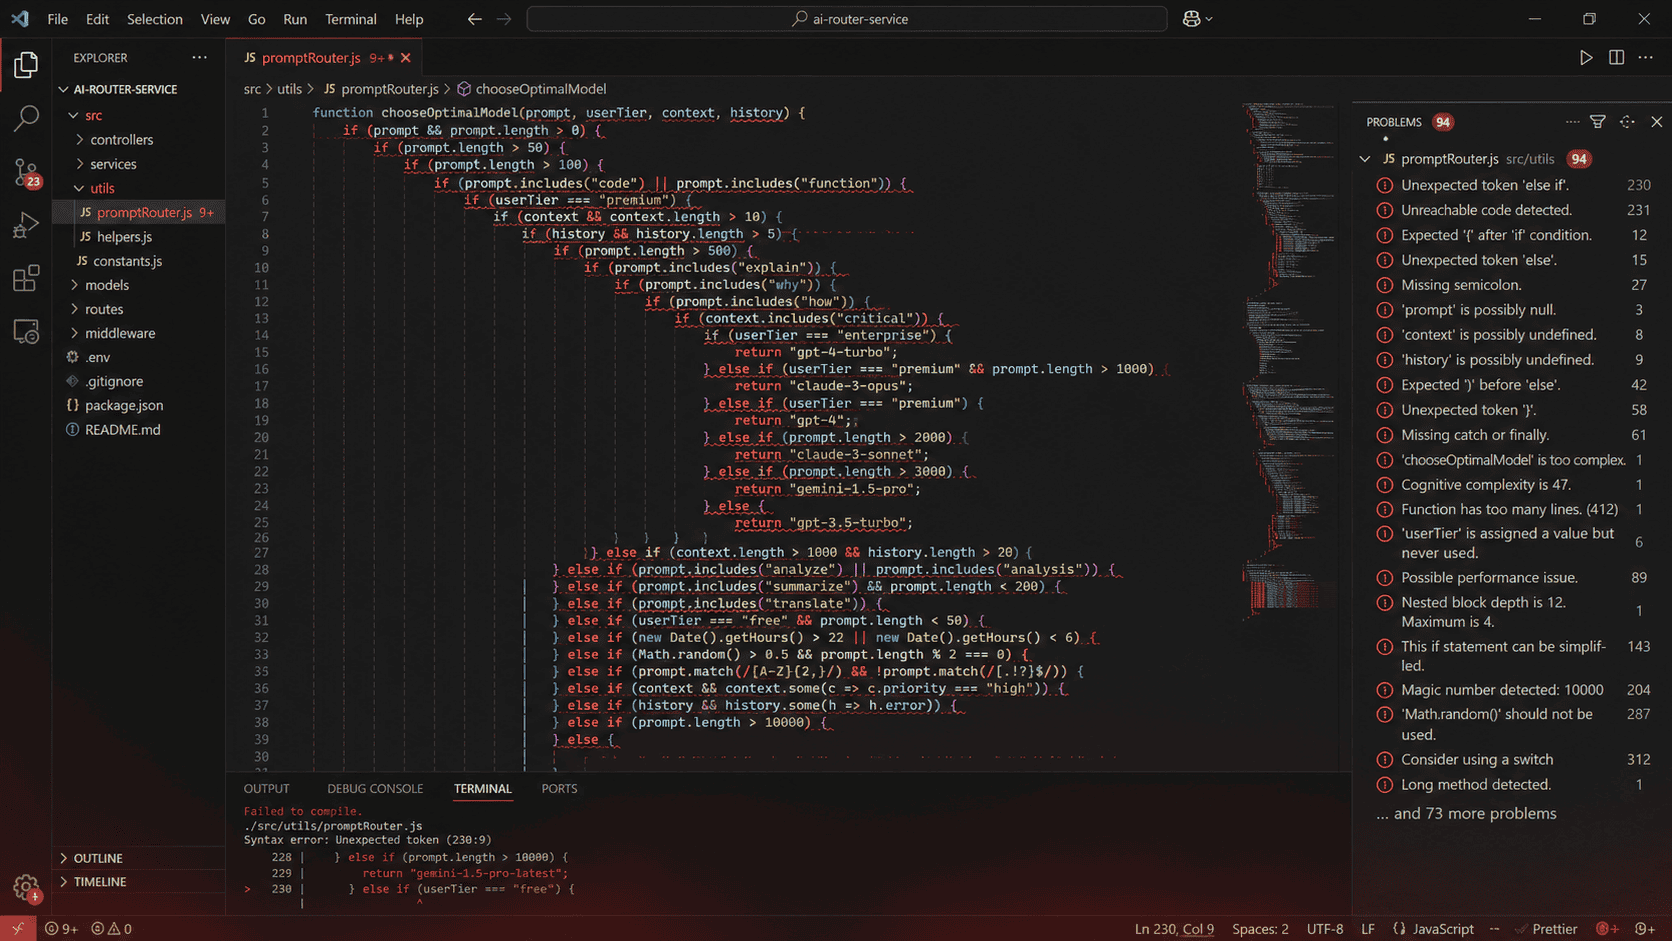
Wrote our own 'AI router'. It is a 400-line if/else on prompt length. It misroutes every Tuesday and nobody can explain why.
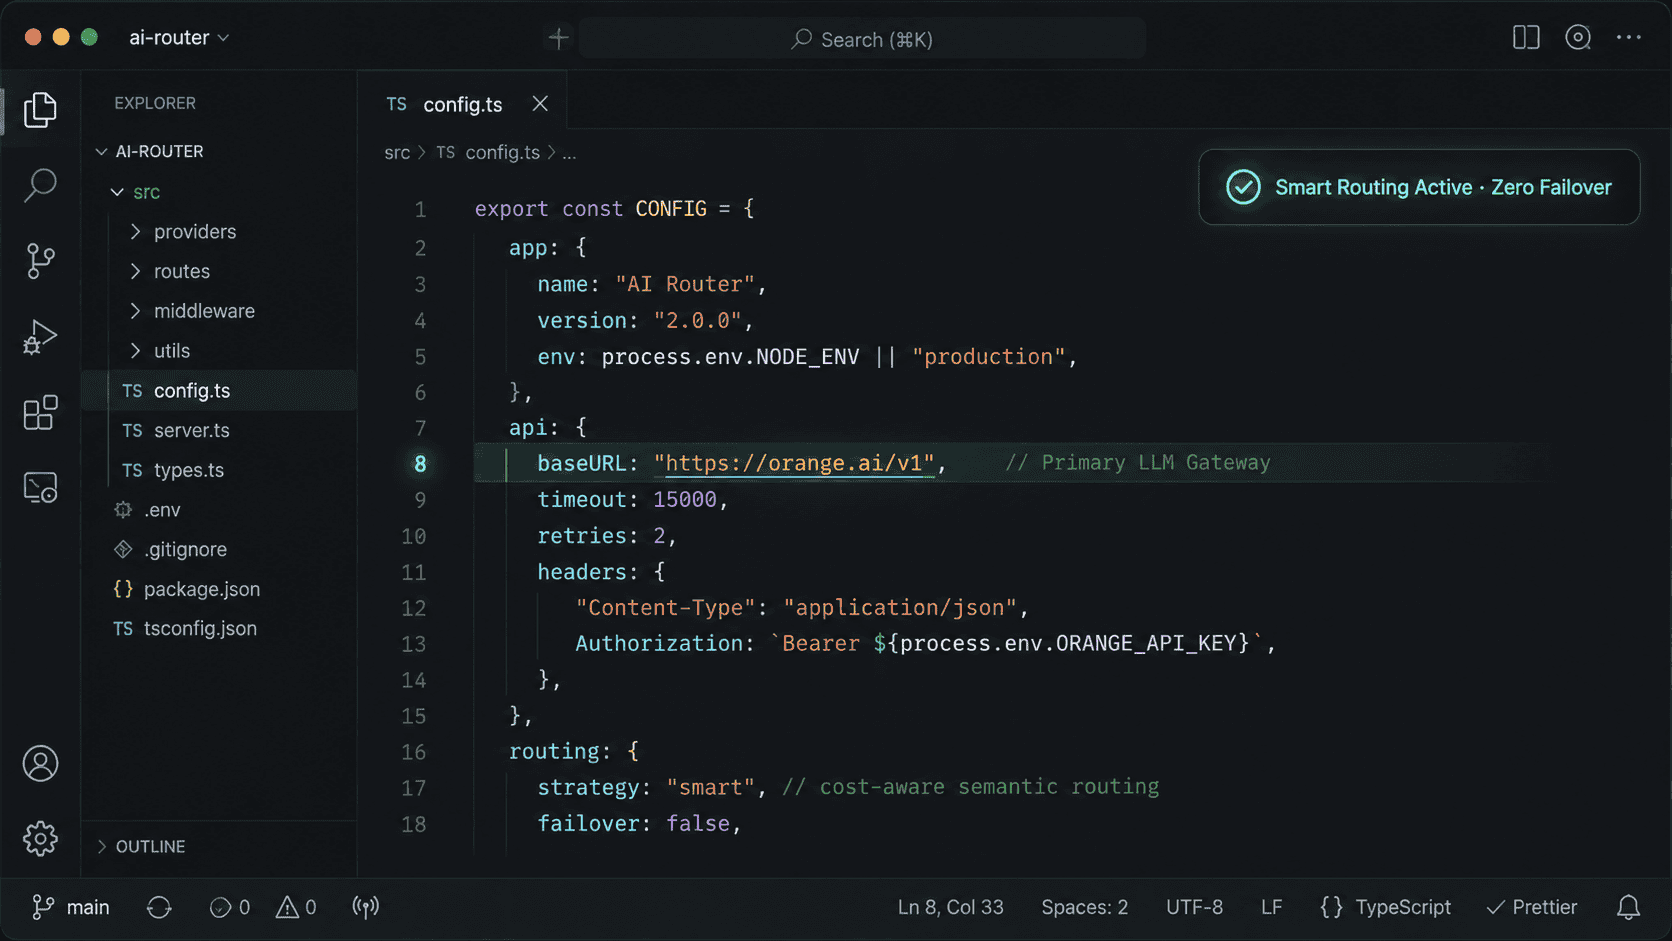
One command setup. Zero refactoring.
An OpenAI-compatible gateway with a cache in front and cost accounting behind. Swap your base URL and nothing else.
Frequently Answered Questions
Pull and run the pre-built Docker container with your provider API key. Then simply change your OpenAI client baseURL to http://localhost:8000/v1 — request shape, streaming, usage blocks, and typed errors remain identical.